
Infrastructure That Works Invisibly
We migrate, automate and manage the infrastructure behind your product so it scales under pressure and never becomes the story.
Cloud Migration · DevOps Automation · Infrastructure Security India, Ireland, Europe and the USA.
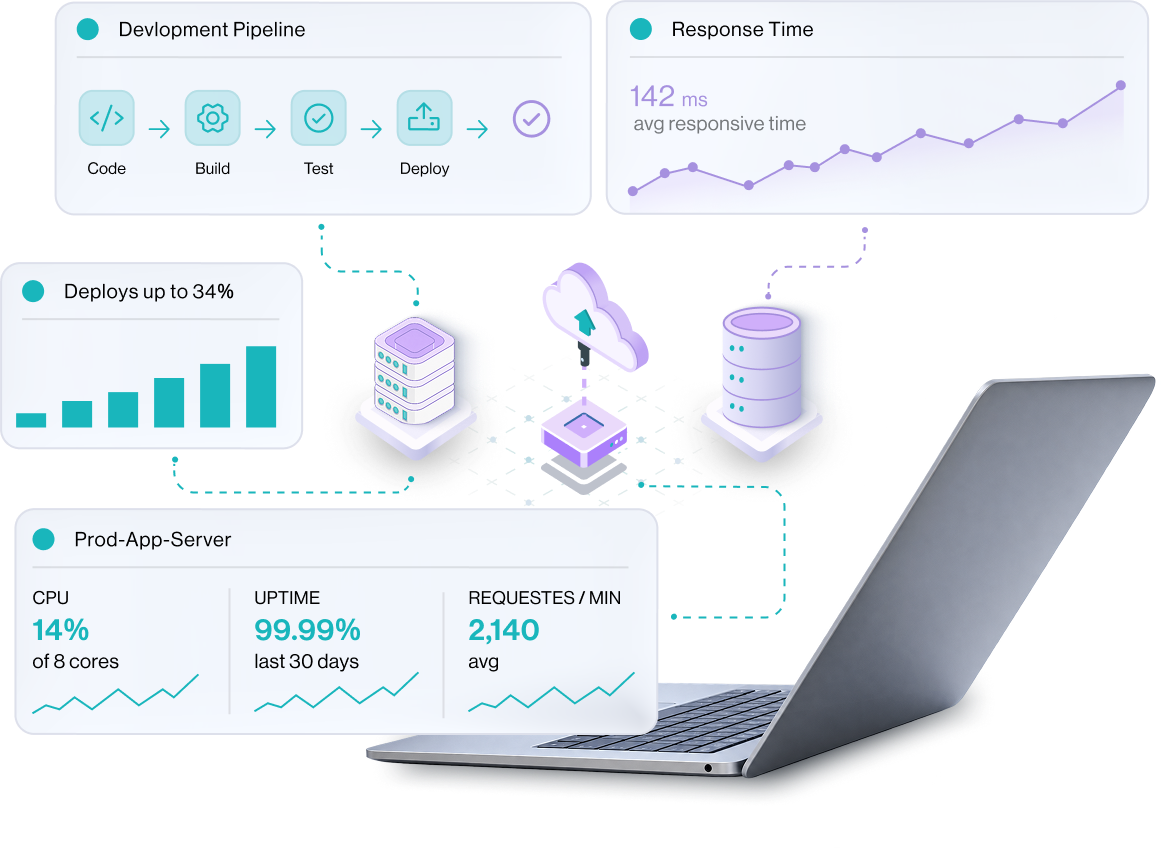


Your product outgrew the systems behind it.
Every growing business hits this bottleneck eventually. The app that ran perfectly at 500 users starts stalling at 5,000. Every new deploy feels a little more stressful than the last. Eventually, keeping the platform stable turns into a 24/7 anxiety with engineers checking system health late into the evening.
None of this means your product failed. It just means your infrastructure hasn't received the same love and attention your product did. We fix the underlying bottlenecks holding you back by slashing costs, tightening security and boosting performance without disrupting what is already working.
Targets Delivered
In infrastructure costs
Migrations completed
During live deployments

What We Build

How We Build and Run Your Infrastructure
We don't guess at your infrastructure. We map it before we build anything.
Every migration or pipeline decision on a Collatzinc infrastructure engagement traces back to how your systems actually behave under real load, not a generic template.
Map Operations
Before we write a line of infrastructure code or build a single pipeline, we analyze how your systems behave under real-world load. We pinpoint where traffic spikes occur, why deployments slow down and what compliance or security constraints we need to respect. This allows us to design an environment tailored to your actual usage patterns instead of handing you a generic template.
Build Systems
Platform choice, infrastructure as code, CI/CD pipeline design and disaster recovery planning are locked in during initial scoping rather than discovered mid-build. We configure provisioning, automation and security in parallel. This guarantees that your entire system is cohesive from the start instead of feeling like a collection of parts bolted on later.
Run and Optimise
We stay deeply involved long after go-live by monitoring performance metrics, trimming cloud spend and testing real-time failovers. This continuous care is how your infrastructure stays resilient as your user base grows, saving you from needing another massive architectural overhaul two years down the road.

Built on the Tools That Scale
Not the frameworks we are just experimenting with. These are the battle-tested technologies we use to run production infrastructure across multiple industries and geographies.
 Cloud Platforms
Elastic infrastructure that scales with your demand. (Our team carries the quiet authority of being AWS Certified Professionals)
- AWS
- Google Cloud
- DigitalOcean
- Azure
 Serverless
Pay only for what you use and scale without managing servers.
- AWS Lambda
 Containerisation
Perfectly consistent environments from local development to live production.
- Docker
 Orchestration
Automated, self-healing container management at scale.
- Kubernetes
 Automation
Infrastructure defined in code to deploy rapidly without configuration drift.
- Terraform
- Ansible
 Delivery
Faster, highly stable releases through automated pipelines.
- CI/CD Pipelines
- Jenkins
- GitHub
Application development and Mobile builds that run on this infrastructure are handled through our Custom Web and Mobile App Development practices
Builder's Insight
View Our WorkWe don't build infrastructure and walk away. We stay hands-on, scaling it alongside the business as it grows.
Collatzinc Engineering Team
View Our Work
Engineering High-Availability Infrastructure for a US-Based Disaster Relief Non-Profit
- USA
- Nonprofit and Logistics
- AWS
- Multi-Environment
- CI/CD

Mission-Critical Logistics: Supporting Active Emergency Responses with Zero Friction
Coordinating disaster relief means handling extreme, unpredictable spikes in traffic. Thousands of field volunteers need to deploy at a moment's notice, and the systems behind them can't hesitate either. For a major national disaster relief operation, volunteer coordination, team scheduling and logistics all run through one mission-critical stack.
We engineered and managed their entire AWS backbone. A resilient multi-environment architecture, built with real-time tracking, holds up when traffic spikes hardest during a crisis. To connect digital operations with physical disaster zones, we built a custom mobile application field teams rely on under extreme conditions.
At active response sites, automated CI/CD pipelines keep development, staging and production fully isolated. Updates ship during live operations without breaking anything. Database provisioning keeps every field platform running, so availability is never a question.
Impact by the Numbers
- Multi-Environment Architecture: Development, staging, and production are completely isolated to guarantee total stability.
- Zero-Downtime Deployments: Critical software updates ship seamlessly without a single disruption to live disaster response operations.
- Flawless Uptime: 99.99% Uptime maintained even during critical, high-stress response windows.
- Unified Management: Multiple core platforms and environments are managed seamlessly across the entire logistics ecosystem.

Trusted to Keep Things Running

Every request delivered on time, detailed monthly reporting and project management, alongside the quality of the work itself.
Leadership team, Food Village
Related Services

eCommerce Solutions
Storefronts and checkout systems built on infrastructure that handles real traffic.

IoT and Connected Systems
Connected device backends built on infrastructure that scales with them.

AI and Data Intelligence
Smart automation and intelligence added to digital systems already built to scale.

Quality Engineering and Testing
Rigorous automated testing and validation for every release your deployment pipeline ships.